Replication is an important topic in economic research or any social science for that matter. This issue is most important when an analysis is undertaken to inform decisions by policymakers. Drawing inferences from null or insignificant finding is particularly problematic because it is often unclear when “not significant” can be interpreted as “no effect.” We recently wrestled with this issue in our paper, “The Effect of the Conservation Reserve Program on Rural Economies: Deriving a Statistical Verdict from a Null Finding,” published in the American Journal of Agricultural Economics. Below is a summary of our findings.
While an inherent bias to publish research with significant findings is widely recognized, there are times when not finding an effect may be more important. For example, suggestive evidence that a policy may not work is arguably more consequential than statistical confirmation that is does. The conundrum produced by null findings is not having any statistical basis for determining whether the true effect is close to zero or if the test is underpowered—that is, unlikely to detect a substantive effect. Our paper developed a method for deriving probabilities for null findings by providing a valid ex post estimate of statistical power. This allows economists and policymakers to more confidently conclude when “not significant” can, in fact, be interpreted as “no substantive effect.”
We demonstrate our method by replicating an analysis from the Economic Research Service’s (ERS) 2004 Report to Congress on the economic implications of the Conservation Reserve Program (CRP). The program, which was signed into law in 1985, was designed to remove environmentally vulnerable land from agricultural production. However, farm-dependent counties experienced both employment and population declines through the economically prosperous 1990s, raising concerns that the program might have cost jobs due to a reduction in agricultural production. Indeed, the ERS report identified worse employment growth in farm-dependent counties with high-CRP enrollments relative to their low-CRP enrollment peers. However, the report was unable to attribute lost employment to CRP enrollments.
While the report failed to identify a statistically significant, negative long-term effect of the program on employment growth, the authors cautioned that the verdict of “no negative employment effect” was only valid if the econometric test was statistically powerful. Replicating the 2004 analysis using new statistical inference methods allowed us to determine whether the tentative 2004 conclusion was correct. Our replication addresses two critical deficiencies that prevent economists from estimating statistical power: 1) we posit a compelling effect size—the level of job losses that would raise concerns regarding the trade-off with environmental benefits–and 2) we estimate the variability of an unobserved alternative distribution using simulation methods. We conclude that the test used in the ERS report had high power for detecting employment effects of −1 percent or lower, equivalent to job losses that would reduce the program’s environmental benefits by a third. An unrestricted test in line with Congress’s charge to search for “any effect” had very low power.
In many circumstances, economists do not have the opportunity to conduct power analysis before research starts. The approaches we suggest can be used to determine power for univariate analyses or multivariate regressions after the fact, provided the data-generating process can be replicated and the effect size of economic significance or policy relevance is stated. Given a range of posited effect sizes, our approach supplements an array of tools to inform decision making in the event of a null finding.”
In the spirit of replication, you can find our data and code in the supporting documentation of the article. If you are not able to access the article, the supplemental materials are also available here. We hope that others confronted with the “null hypothesis lacking error probability” conundrum will consider using the methods as a tool for making null findings potentially more informative, and for making our toolkit of applied econometric methods more useful for decision-making.
Jason P. Brown is an assistant vice president and economist at the Federal Reserve Bank of Kansas City. Dayton M. Lambert is a professor and Willard Sparks Chair, Department of Agricultural Economics, Oklahoma State University. Timothy R. Wojan is a senior economist, USDA, Economic Research Service. The opinions expressed are those of the authors and are not attributable to the Federal Reserve Bank of Kansas City, the Federal Reserve System, Oklahoma State University, the Economic Research Service, or USDA. Correspondence can be directed to Jason Brown at Jason.Brown@kc.frb.org.
[From the website of the journal Japanese Journal of Political Science, published by Cambridge University Press]
The website of the Japanese Journal of Political Science recently announced that it was allowing authors to select “results-blind” reviewing as an alternative to traditional “full paper” review (see below).
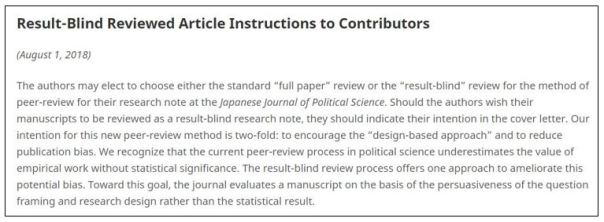
This is in addition to the journal’s policy of encouraging the submission of both “reanalysis” and “replication” manuscripts.

[From the article, “Will Facebook’s New Research Initiative Make The Replication Crisis Worse?” by Kalev Leetaru, published online at Forbes.com]
“The era of “big data” has transformed our understanding of the human world, making it possible for researchers to study billions of users at once, while at the same time making it impossible for other researchers to replicate their work. The ever-larger datasets that increasingly define modern quantitative social science are controlled by an ever-shrinking number of researchers that have exclusive access to the digital riches of our modern world. Facebook’s new academic research initiative with Social Science One was supposed to fix all of this, granting researchers across the world access to the private data of Facebook’s two billion users to mine, but the unanswered question is how initiatives like Social Science One will address the replication crisis.”
“…When it comes to the replication process, however, Social Science One has remained nearly entirely silent.”
[From the blog, “The uncanny mountain: p-values between .01 and .10 are still a problem” by Julia Rohrer, posted at The 100% CI]
“Study 1: In line with our hypothesis, …, p = 0.03.”
“Study 2: As expected, … p = 0.02.”
“Study 3: Replicating Study 2, … p = 0.06.”
“Study 4: …qualified by the predicted interaction, … p = 0.01.”
“Study 5: Again, … p = 0.01.”
“Welcome to the uncanny … p-mountains, one of the most scenic accumulations of p-values between .01 and .10 in the world! Over the course of the last years, many psychologists have learned that such a distribution of p-values is troubling (see e.g. blog posts by Simine Vazire and Daniël Lakens) and statistical tools have been developed to analyze what these distributions can tell us about the underlying evidence (Uli Schimmack’s TIVA, p-curve by Simonsohn, Nelson and Simmons p-curve)—as it turns out, quite frequently, the answer is not good news.”
“However, the uncanny p-mountains can still be seen in journal articles published in 2018. And this is probably no surprise given that (1) our intuitions about something as unintuitive as frequentist statistics are often wrong and (2) many researchers have been socialized in an environment in which such p-values were considered perfectly normal, if not a sign of excellent experimental skills. So let’s keep talking about it!”
[From the article “Q&A Adam Russell: Can automated tools reliably rate research reproducibility?” by Dalmeet Singh Chawla, published at natureindex.com]
[From the blog “How Freely Should Scientists Share Their Data?” by Daniel Barron, published at blogs.scientificamerican.com]
“At the beginning of graduate school, I decided I wanted to study how epileptic seizures damage the brain. I was in something of a pickle: I wanted to use magnetic resonance imaging (MRI) to study this damage, but I didn’t have access to MRI data of patients with epilepsy. Even if I had that data, I didn’t know much about programming or mathematics or physics, so I couldn’t have created ex nihilo the software tools to analyze the data anyway. So, I was driven and energetic and wanted to study epilepsy, but I didn’t have the data or tools to work with.”
“… At around this time, I first heard about the Open Science movement—the increasingly popular belief that scientific methods and data should be freely available. The overall goal is to make science as democratic and accessible as possible. To do this, Open Scientists make their data, methods and code (computer programs that analyze data) openly available to the public. Open Scientists also share with their colleagues, which, as I discovered as a graduate student, can be a great boon to science.”
“I also heard cautionary tales that the Open Science movement had a dark side, that “openness” had, at times, devolved into bullying and theft. Some compared the Open Science movement to Communism: good in principle, impossible in practice. In informal settings—at dinner, over drinks—I was reminded that science was a competitive business.”
“But I didn’t worry that much until early this July.”
[From the abstract of the paper, “A Unified Framework to Quantify the Credibility of Scientific Findings”, by Etienne LeBel, Randy McCarthy, Brian Earp, Malte Elson, and Wolf Vanpaemel, published in the journal, Advances in Methods and Practices in Psychological Science]
[From a letter to the editor by Arthur C. Evans Jr., chief executive of the American Psychological Association]
“We are proud that psychologists are at the forefront of those calling for reassessment of earlier research. The American Psychological Association has embraced the move toward more open science, encouraging the scientists whose work we publish to deposit their data in online repositories for other researchers to scrutinize and reanalyze.”
“Recognizing that this process depends on broad awareness of data availability, we have also begun to mark articles with badges denoting that the study methods were preregistered and that the author is sharing data or related materials.”
[From the blog “A Great Day for Open Policy Analysis” by Fernando Hoces de la Guardia (BITSS Postdoc) posted at http://www.bitss.org]
“Earlier this year, I headed over to the CBO [U.S. Congressional Budget Office] to share my efforts to “reverse engineer” one of their debated reports, on the projected effects of a minimum wage increase. I recreated the CBO analysis in a fully transparent and reproducible format, using tools that are now common in the open science community.”
“Analysts at the agency seemed very receptive to the idea of OPA [Open Policy Analysis]… So you can imagine how excited I was to see the following tweet from CBO yesterday.”

[From the article “There Is More to Behavioral Economics Than Biases and Fallacies” by Koen Smets, published at the Behavioral Scientist]
“In some cases, follow-up studies have unmasked outright frauds, like Diederik Stapel, who fabricated and manipulated data to show that meat eaters are more selfish than vegetarians. Similarly, follow-up studies have exposed the dubious-but-perhaps-not-quite-fraudulent methods of people like Brian Wansink, whose papers have repeatedly been found to contain inaccuracies and errors undermining the validity of his conclusions.”
“But other “failed replications” are not quite so unequivocal once one looks behind the headlines. Human behavior is complex, and sensitive to context and circumstances. It is unwise to take an observed effect as gospel (we’ll come back to that in a moment), but it is equally unwise to take a single failed replication as proof that the originally observed effect does not exist.”
“…. We need to continue to replicate, in different circumstances, and build up the model of human cognition and behavior—much like how a sculpture is made. Start with a rough wire mesh, add some dollops of clay, stand back and observe, trim and refine. Doesn’t quite fit? Remove and start again. The difference is that a sculpture usually gets finished in the end. Behavioral economics will be a work in progress for a long time to come. But with the right sculptors, there is hope yet for a masterpiece.”


You must be logged in to post a comment.